Tag: sql server

  • The Backup Process

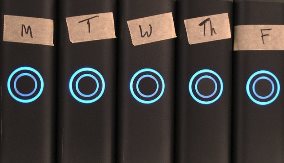
    This used to be my backup process. Five copies, one for each day of the week.
    This used to be my backup process. Five copies, one for each day of the week.

    I was reading Scott Hanselman’s post onThe Computer Backup Rule of Three, and I completely agree with him. If things are important, three copies are the minimum you should keep. I have had backups before, but I’ve found that when something breaks, like a tape drive or hard drive, I might not get to replace it right away. Usually this is procrastination, or as it’s more commonly known, laziness. During that window of opportunity, I’ve had Mr. Murphy strike. My inherent paranoia of having that second extra copy has saved me, both personally (at home) and professionally (at work).

    All too often I run into DBAs that seem to trust and assume their backups and processes are very reliable. After setting up a backup process, usually to disk, and testing it with a restore on another system, they assume it will work in the future. It should, but there is always the chance something will fail at some point in time. There’s the chance that some hardware failure or software reconfiguration will cause an issue with your process. There’s also the simple chance that your I/O system might introduce corruption into your backup files.

    If you aren’t regularly testing your processes, you can’t be sure they are working as they have in the past. The ideal environment would perform a restore of every backup file taken, every day, but that isn’t always possible. However restoring a random backup once every month or two will help you to ensure your backup, and restore, processes, have the best chance of succeeding when you actual need to perform them because of a disaster.

    This isn’t hard to script and automate, but it is something you need to do periodically. However even if you automate restores of all your databases, make sure you still practice your manual skills regularly. Automation might not work in a disaster situation, but those quarterly practice sessions restoring a database to a point in time with a tail log might just relax you when a crowd in your cube is asking if the database will be back up soon.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Customizing SSMS – Hiding the panels

    This is a short series on some customizations in SSMS to make it visually more appealing.

    As a presenter, I’ve learned how to change the way Management Studio (SSMS) looks to make it easier for people to see the screen on a projector. I had wrongly assumed that so many people knew many of these tricks, which is a poor attitude on my part. That should be especially apparent as I saw a presentation recently where the speaker didn’t know how to make things easier to see.

    Note that I often caution writers not to assume too much from the reader, and here I took it one step further, assuming some topics weren’t worth writing about.

    Here’s one that I heard asked recently: how do you hide the side panels in SSMS?

    The Default View

    Here’s what SSMS looks like for most people.

    ssms_a

    The Object Explorer takes up a good portion of the screen on the left. For some people, they may have this:

    ssms_b

    Or even this:

    ssms_c

    In the last two images, the Solution Explorer and Properties panes are on the right. If you have these panes open, you might find yourself squeezing a query into a small space in the middle. If your resolution is 1024×768 (standard for many projectors), you might get very little on the screen.

    Customizing

    There’s a way to clean things up quickly and easily. All of these panes have this item in their upper right sides:

    ssms_d

    If you click the middle, pin icon, the “Auto Hide” will be enabled, and the panes will slide to the side. They’ll still be there, but now they’ll be in a side bar, like the Object Explorer is below:

    ssms_e

    If I hover the mouse over the “Object Explorer” button on the side, it will appear, or I can click it.

    I can always use the “View” menu at the top as well (or a shortcut) to expose any of these panes. However when I’m presenting, or want to make a quick change, the “auto hide” feature works very well for me.

  • The Gambler

    I'll be speaking here. Come shake my hand if you can come and register with the code "Jones"
    I’ll be speaking here. Come shake my hand if you can come and register with the code “Jones”

    In April of this year, the SQL Intersection conference is coming to Las Vegas. I’m speaking, along with Grant Fritchey and many others. It’s a fun event, in a city with a huge variety of things to do in the evenings after a full day of SQL Server sessions. At night I tend to look for networking chances to met new people and catch up with friends at night, though there have been a few times a comedy show has enticed me away from my hotel. I like Las Vegas, though I’m not a gambler. Despite the fact that most people think of visitors looking for their chance to sit at a table with dice or cards, there are many of us that go for other activities.

    I was at in a session recently and heard a speaker recommend that the audience run DBCC checks regularly. That’s good advice, and it’s what I recommend in my sessions as well. A person in the audience raised their hand and politely disagreed, saying that they almost never run DBCC CHECKDB. This person found it to be a waste of resources since they’d never encountered corruption in their career, and hadn’t known anyone in over a decade that had experienced on a SQL Server system. This person asked the speaker how many times the speaker had seen corruption (five was the answer) and then said across thousands of days of backups, it just wasn’t worth the resources to run DBCC CHECDB.

    If you feel that way, then you’re a gambler. You are accepting a higher level of risk than I do, and higher than I recommend. Consistency checks are designed to help us catch corruption. Since we never know when it will occur, we want to detect is ASAP so that we avoid, or at least minimize, data loss. If you run those checks and never experience corruption, those checks are insurance payments you’ve made and never needed to file a claim. However if you don’t run those checks, and experience corruption, you’ve placed a bet you’ve lost. Whether or not that cleans you out depends on the data loss your organization experiences and their tolerance for that loss. I’d seriously consider this a career limiting, or employment terminating, event, especially if the best practice recommendation from Microsoft and many experts is to run DBCC checks.

    I don’t recommend skipping your DBCC checks, but if that’s how you feel, think about coming to SQL Intersection (register with the code “Jones” to support me). You might enjoy that gaming tables at night, and I know the other speakers and myself would welcome the chance to change your mind about skipping DBCC checks during the day.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.

  • Self Describing Databases

    Self describing databases would be very, very handy.
    Self describing databases would be very, very handy.

    When contained databases were introduced in SQL Server 2012, I thought they were a very nice enhancement to the platform. The idea of having security managed inside the database, thereby removing the problem of orphaned users, was something I looked forward to. Preventing collation conflicts is also a nice benefit, though I’ve never had a problem with this issue. However I was, and still am, hoping that this was just the beginning of what a contained database would be. I had a vision of a self-describing database.

    There are many things that we need to manage with databases: maintenance, backups, auditing, performance statistics, alerts, and more. Most of these are set up at the instance, but I’ve never quite understood why. Software should help us work more efficiently, and work with us, not against us. So many of these administrative items are dependent on the needs of a particular database or application, but we perform all these actions at the instance level.

    Backups are an example of a database dependent item, as we constantly teach new DBAs. However the backup plans are set at the instance level, and if you have disparate requirements for different databases, these result in different backup plans. The MSDN documentation says we should even have a manual for each database. If that’s the case, why is the information about a database backup stored outside of the database? I think it would make more sense for the backup plan to be stored in the database, and when the database is attached, or the plan created, the instance would read this plan and create the necessary jobs. If we detached the database, the jobs would be removed. We run recovery in each database, couldn’t that serve to enable or disable any alerts, jobs, etc. for any database that wasn’t accessible?

    I envision much more than just backups as being a part of the database. Every action we need to manage in a database from alerts to auditing, should be stored there. Let the Agent on the instance read the database and automatically set up the jobs needed. If there are conflicts with scheduling, alert the DBA at the instance level, but keep the metadata about the needs of the database in the database. It would make consolidation, or movement of databases much simpler. It would also fit with the idea of a database service, rather than a database server.

    Steve Jones


    The Voice of the DBA Podcasts

    We publish three versions of the podcast each day for you to enjoy.